Commercial vs SEO Web Crawlers Explained: How They Work & Why Hosting Matters
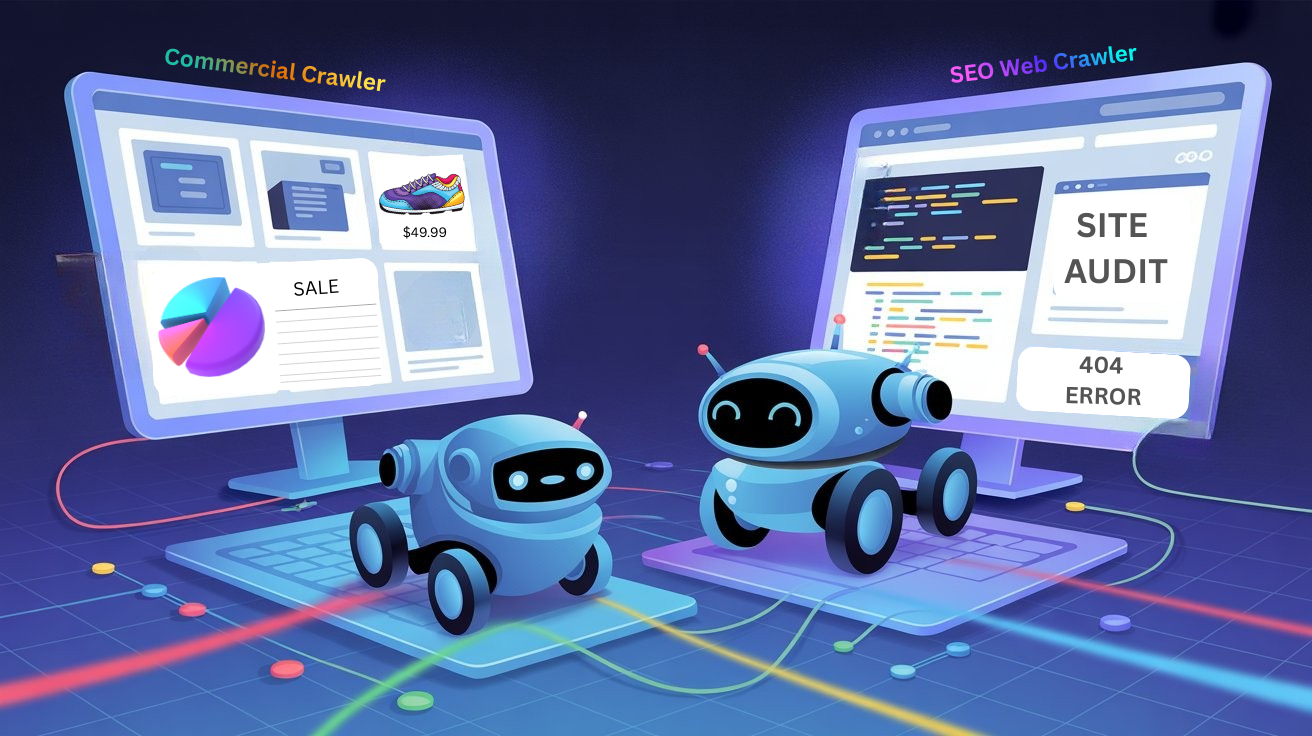
Every search result, price comparison, content update, and performance report relies on automated systems that continuously scan and analyze online information. These automated programs help businesses track trends, monitor competitors, understand user behavior, and improve digital performance.
As online competition grows, the ability to collect and interpret web data efficiently becomes increasingly important. Whether for visibility, analytics, or strategic decision-making, web crawling technologies play a vital role in shaping how organizations operate and compete in today’s digital world.
TL;DR
- Commercial Web Crawlers are designed to collect large-scale data from across the internet for AI training, analytics, market research, and competitive intelligence.
- SEO Web Crawlers are built to analyze individual websites and identify technical SEO issues that affect search engine rankings.
- Commercial crawlers focus on data extraction, while SEO crawlers focus on website auditing and optimization.
- Businesses use commercial crawlers for data insights, whereas website owners use SEO crawlers to improve visibility and search performance.
Difference Between Commercial Web Crawlers and SEO Web Crawlers
Web crawlers may function similarly at a technical level, but their objectives, scope, and impact vary significantly depending on their intended use. Understanding these differences helps businesses choose the right tool for their digital strategy.
1. Primary Purpose
SEO web crawlers are designed to strengthen your online visibility. They scan your website the same way search engines do, uncovering technical issues, indexing problems, broken links, and duplicate content. Their ultimate goal is simple: help your website perform better in search results, attract more organic traffic, and deliver a smoother user experience.
Commercial web crawlers, on the other hand, are focused on gathering valuable market data at scale. Businesses use them to track competitor pricing, monitor product trends, analyze reviews, and collect large volumes of publicly available information across multiple websites. Instead of optimizing one site, they power smarter business decisions, competitive intelligence, and strategic planning.
2. Scope of Crawling
SEO Crawlers
- Usually crawl a single website or domain
- Analyze internal links, page structure, and metadata
- Identify on-page and technical SEO issues
They operate within a controlled scope, typically limited to the audited website.
Commercial Crawlers
- Crawl multiple websites across industries
- Collect structured and unstructured data
- Operate at scale, often scraping thousands or millions of pages
They are designed for broader, cross-platform data extraction.
3. Data Collected
SEO Crawlers Collect
- Broken links
- Duplicate content
- Meta tags and headings
- Page load performance
- Crawl errors
- Redirect chains
- XML sitemap issues
This data helps optimize rankings and user experience.
Commercial Crawlers Collect
- Product prices
- Competitor listings
- Customer reviews
- Market trends
- Inventory availability
- News and industry updates
This data supports pricing strategies, research, and forecasting.
4. Impact on Business Strategy
SEO Crawlers Improve
- Organic traffic
- Search rankings
- Technical site health
- User experience
- Conversion rates
They directly impact marketing and visibility.
Commercial Crawlers Improve
- Competitive Advantage – Access large-scale web data to monitor competitors and market activity.
- Pricing Accuracy – Collect pricing data across multiple sources to support dynamic pricing strategies.
- Market Awareness – Track trends, product availability, and industry changes across the web.
- Strategic Decision-Making – Use collected data to guide business strategies and planning.
- Business Intelligence Reporting – Convert extracted web data into insights for analytics and reporting.
They influence broader business planning.
5. Technical Requirements
SEO Crawlers
- Moderate server resources
- Typically lighter crawling load
- Lower infrastructure complexity
Often used through SaaS SEO platforms.
Commercial Crawlers
- High server performance
- Proxy management systems
- Advanced scraping infrastructure
- Higher bandwidth usage
They often require strong hosting environments for large-scale operations.
6. Compliance and Ethical Considerations
SEO Crawlers
- Follow search engine guidelines
- Respect robots.txt directives
- Designed for auditing purposes
Commercial Crawlers
- Must consider legal and ethical boundaries
- Often require compliance review
- May involve rate limiting and proxy rotation
Improper implementation can lead to IP blocking or legal risks.
Scalable WordPress Cloud Infrastructure for High Crawl Activity
For websites experiencing high crawl frequency or traffic spikes, WordPress Cloud Hosting provides scalable infrastructure that adapts instantly to demand. With isolated resources and enhanced performance layers, it ensures uninterrupted crawling, faster indexing, and stable website performance under load.
Types of Commercial Web Crawlers
Commercial web crawlers serve different business objectives depending on how organizations use large-scale web data. Each category below reflects a specific operational focus and data collection strategy used in enterprise environments.
1. Enterprise Data Crawlers
Designed to crawl large portions of the internet, these systems gather structured datasets used for trend analysis, research, or training large language models. They provide broad visibility across many domains.
2. Competitive Intelligence Crawlers
These crawlers track competitors’ websites for changes in pricing, content, product listings, or service updates. Retailers and product teams use them to stay ahead of market movements.
3. Price & Product Monitoring Crawlers
Common in eCommerce, these bots scan product pages across many stores to monitor pricing, availability, and product details in real time.
4. Brand & Media Monitoring Crawlers
These crawlers scan news sites, blogs, and social platforms to collect mentions of brands or topics. They support reputation management and public relations efforts.
5. Compliance & Security Crawlers
Used to check that web content and internal systems meet regulatory and security standards, especially in industries like finance and healthcare.
6. AI / Research Crawlers
Large datasets like Common Crawl are generated by crawlers used in AI model training, academic research, and indexing massive amounts of web content.
Real Examples of Commercial Web Crawlers
Here are some well-known commercial crawlers and what they actually do:
1. Common Crawl (CCBot)
Common Crawl collects large portions of the public web every month and provides free datasets. Researchers and AI companies use this data to study web trends and train machine learning models.
2. Diffbot
Diffbot uses AI to turn web pages into structured data. Instead of just collecting text, it identifies products, companies, people, and articles for business intelligence use.
3. Scrapy-Based Crawlers
Scrapy is a tool developers use to build custom bots. If you see “Scrapy” in your logs, it usually means someone created a specific crawler to extract targeted data from your site.
4. Dataminr Crawlers
Dataminr scans the web in real time to detect breaking news and important events. Businesses and government agencies use it for early risk alerts.
5. Meltwater & Talkwalker Crawlers
Meltwater and Talkwalker monitor news sites and blogs to track brand mentions and public sentiment.
6. Corporate Compliance Crawlers
Used by legal and cybersecurity firms to detect copyright violations, brand misuse, or leaked company data online.
Types of SEO Web Crawlers
SEO crawlers focus on one website at a time and help website owners or marketers understand how search engines interpret and index their pages.
1. Search Engine Indexing Crawlers
These are the bots used by major search engines to discover and index content.
- Examples: Googlebot, Bingbot, YandexBot
They follow site links, read metadata, and decide which pages appear in search results.
2. Technical SEO Crawlers
These tools crawl websites to find structural and technical issues such as broken links, missing tags, and redirect errors. Popular tools include Screaming Frog and Sitebulb.
3. Performance & Structure Crawlers
Tools like DeepCrawl (now Lumar) map site architecture and reveal structural issues that affect SEO, such as orphaned pages or sitemap gaps.
4. Content Auditing Crawlers (tools)
SEO platforms like SemrushBot or AhrefsBot scan pages for content quality issues such as thin content, duplicate text, or poor keyword usage.
5. SEO Marketing & Analytics Crawlers
These are part of comprehensive SEO suites that provide backlink profiles, keyword data, and competitive benchmarking. They help marketers understand how their site performs relative to competitors.
Other Crawler Categories (Extended Research)
In addition to commercial and SEO crawlers, there are other bot types that often show up in web logs:
1. Social Media Crawlers
Used by platforms like Facebook and LinkedIn to fetch metadata (title, image, description) for shared links.
2. Malicious / Rogue Crawlers
These bots scrape content, harvest emails, or attempt brute-force attacks. They ignore crawl rules and should be blocked for security.
3. Open-Source & Custom Crawlers
Frameworks such as Scrapy and Apache Nutch enable developers to build their own crawlers for specific internal use cases, research, or data extraction.
Challenges of Commercial Web Crawlers
1. Handling Massive Volumes of Information
Commercial crawlers typically gather data at scale, often pulling information from thousands of pages in a single operation. Storing, organizing, and processing this amount of data requires advanced systems and well-structured pipelines. Without strong data management practices, businesses may end up with cluttered datasets that are difficult to analyze or apply strategically.
2. Technical Load and Operational Pressure
Running commercial crawlers at high speed demands substantial computing resources. Continuous requests, data parsing, and structured extraction can consume significant bandwidth and processing capacity. At the same time, if crawling intensity is not properly controlled, it can strain the servers of target websites, potentially affecting their performance.
3. Defensive Systems and Restricted Access
Many websites implement protective technologies to detect and restrict automated traffic. Security layers such as rate limiting, behavioral monitoring, and traffic filtering can interrupt or block crawling activity. This makes consistent data collection challenging, especially in competitive markets where platforms actively guard their information.
4. Risk of Data Misuse and Business Impact
Commercial crawling is often used to monitor pricing, products, and market trends. However, when extracted data is redistributed or replicated without permission, it can lead to unfair competition, brand dilution, or loss of proprietary advantage. Businesses must consider how collected data is used and whether it respects ownership boundaries.
5. Regulatory and Legal Exposure
The legality of automated data collection varies depending on region, industry, and the nature of the information gathered. Even publicly available content may fall under copyright or data protection regulations. Organizations using commercial crawlers must carefully evaluate compliance requirements to avoid legal complications.
6. Inconsistent or Context-Limited Data
Web content is frequently dynamic and personalized. Prices may vary by region, content may change based on user behavior, and some elements load only through scripts. As a result, crawlers may capture partial or context-specific snapshots that do not reflect the full picture, potentially affecting business decisions.
7. Limited Transparency in Crawling Practices
Not all commercial crawlers clearly identify themselves during data collection. Some use distributed networks or masked identities to avoid detection. This lack of transparency can raise trust issues and make it difficult for website administrators to distinguish legitimate monitoring from malicious scraping attempts.
Challenges of SEO Web Crawlers
1. Limited Crawling Priority and Resource Allocation
Search engines do not scan every page of a website with equal attention. They assign a limited amount of crawling activity based on factors like authority, structure, and update frequency. If a website contains duplicate paths, weak internal linking, or unnecessary URL variations, important pages may be discovered slowly or skipped altogether, delaying visibility in search results.
2. Technical Errors That Disrupt Indexing
SEO crawlers rely heavily on technical signals to understand how pages should be treated. Misused canonical tags, incorrect redirect chains, blocked directories, or unintended noindex instructions can confuse crawlers and prevent pages from appearing in search listings. Even small technical mistakes can significantly reduce organic reach.
3. Heavy Audit Activity and Server Pressure
In addition to search engines, multiple SEO analysis tools may crawl a website to evaluate performance, backlinks, and structural health. When audits run frequently or simultaneously, they can generate a surge in automated requests. On large or resource-limited servers, this can temporarily affect load times and overall site stability.
4. Difficulty Interpreting SEO Reports
SEO crawling tools often produce extensive reports filled with warnings, suggestions, and performance indicators. Without proper expertise, it can be difficult to determine which issues are critical and which are minor. Misjudging priorities may lead to time being spent on low-impact improvements while more serious indexing problems remain unresolved.
5. Misleading or Context-Less Error Flags
Not every issue identified by an SEO crawler indicates a genuine problem. Some pages are intentionally restricted, redirected, or excluded from indexing for strategic reasons. When these intentional settings are treated as errors, it can result in unnecessary changes that disrupt the overall optimization strategy.
6. JavaScript and Dynamic Content Challenges
Modern websites frequently depend on scripts to load content dynamically. While major search engines have improved rendering capabilities, not all SEO tools fully replicate this process. As a result, crawlers may miss important elements, creating gaps between what users see and what technical reports display.
7. Managing Bot Access Without Blocking Search Engines
Website owners must carefully configure security rules to block harmful bots while allowing legitimate search engine crawlers to operate freely. Overly strict firewall settings or misconfigured bot filters can unintentionally restrict indexing, leading to ranking drops or removal from search results.
How Hosting Impacts Commercial and SEO Web Crawlers?
- Your hosting environment plays a key role in how efficiently web crawlers interact with your website.
- For commercial web crawlers, fast and scalable hosting ensures smooth data extraction without timeouts or performance issues.
- Strong server resources help handle high-frequency crawl requests without slowing down your website or affecting user experience.
- Proper security configurations allow controlled crawler access while preventing unwanted or malicious traffic.
- For SEO web crawlers, hosting speed and uptime are essential for effective crawling and indexing.
- Faster servers allow search engines to crawl more pages in less time, improving indexing efficiency and search visibility.
- Reliable infrastructure reduces errors, downtime, and slow responses that could negatively affect search rankings.
- Optimized hosting with SSD storage, caching, and stable performance creates a crawler-friendly environment that supports better SEO performance and consistent data processing.
Built for Stable Crawling Performance
Your website’s crawl performance depends heavily on server stability. Our Shared WordPress Hosting is designed with a strict no resource overselling policy, ensuring every account receives dedicated CPU and memory allocation. This prevents overcrowding, maintains consistent speed during crawl activity, and supports smooth indexing by search engines. The result is reliable performance for both your visitors and automated crawlers.
Read this guide to learn more about optimizing your crawl budget
Frequently Asked Questions (FAQs)
1. What is the main difference between commercial and SEO web crawlers?
SEO web crawlers analyze a single website to improve search visibility and fix technical issues, while commercial web crawlers collect large-scale market data across multiple websites for competitive intelligence and business strategy.
2. Can commercial web crawlers affect my website performance?
Yes, high-frequency crawling can increase server load. Without optimized hosting, this may slow response times or degrade the user experience.
3. How does hosting impact SEO crawling?
Fast, stable hosting enables search engine bots to crawl more pages efficiently. Better uptime, SSD storage, and optimized server response improve indexing speed and search visibility.
4. Why is crawl budget important for SEO?
Search engines allocate limited crawl resources to each website. If your site has technical issues or slow server responses, important pages may not be crawled or indexed quickly.
5. Should I block commercial crawlers?
It depends on your business goals. Some crawlers provide legitimate monitoring or analytics value, while others may scrape data aggressively. Proper bot management and rate limiting help maintain control.
6. Is cloud hosting better for websites with high crawl activity?
Cloud hosting is often ideal for high-traffic or large websites because it offers scalable resources. It can handle crawl spikes and traffic surges without performance drops.
7. How can I make my WordPress site crawler-friendly?
Use optimized hosting, maintain clean internal linking, fix technical SEO errors, improve site speed, and configure robots.txt correctly to ensure efficient crawling.
About the Author: Jason-Pat
Founder & CTO at AccuWebHosting.com. He shares his web hosting insights at AccuWebHosting blog. He mostly writes on the latest web hosting trends, WordPress, storage technologies, Windows and Linux hosting platforms.